







提示词
眼下最能带来超额收益的做法简单到大多数人永远不会去做……

打造一套适合你自己的 harness

它能让你的 AI 输出质量和速度提升 10 倍。

把这一个提示词粘贴到你的智能体中:

---------提示词开始----------------

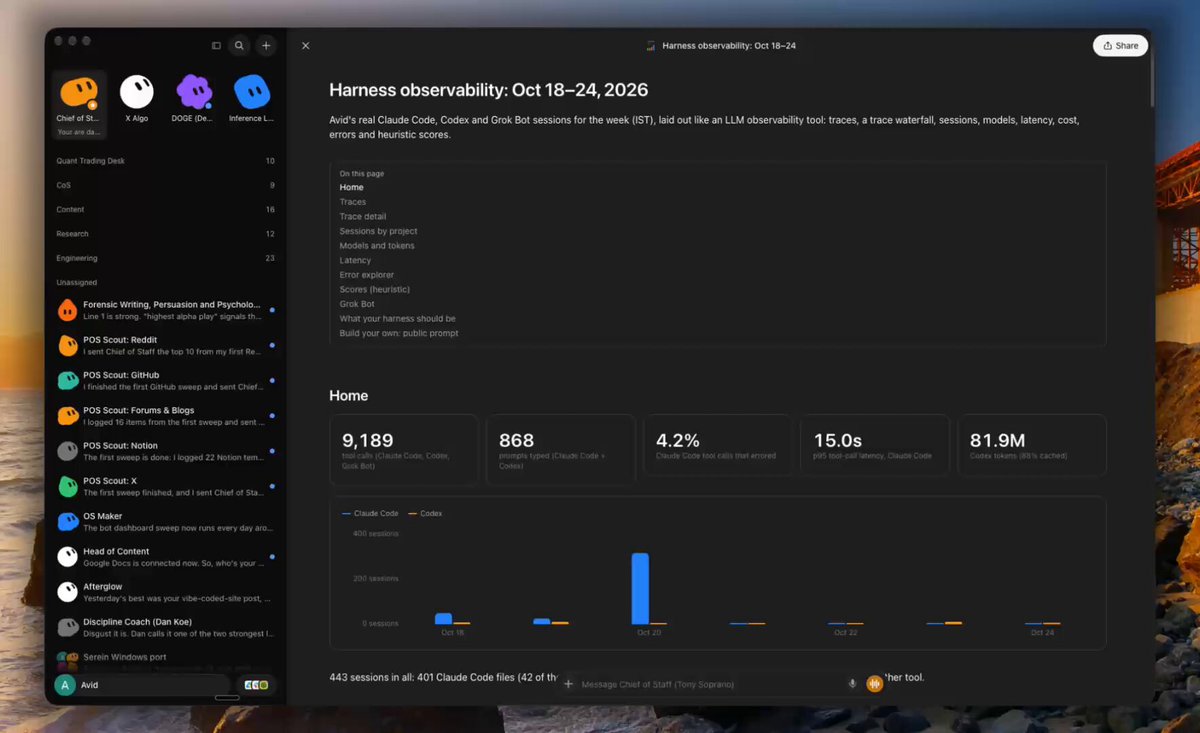
根据我过去 7 天的 AI 编程会话,为我构建一个 Langfuse 风格的可观测性看板。

数据来源(本地读取,只读):
- Claude Code: ~/.claude/projects/**/*.jsonl
- Codex: ~/.codex/sessions/**/*.jsonl(以及 ~/.codex/history.jsonl)
绝不打印机密信息、密钥或完整提示词文本。片段最多 10 个词,并移除其中的密钥、路径、URLs 和长 ID。

步骤 1. 编写一个仅使用 Python 标准库的脚本,按工具分别计算:
- 每日会话数、用户提示词数、按工具名称统计的工具调用数、按工具和错误类型统计的失败工具调用数
- 使用过的模型、每个模型每天的 token 数(输入、输出、缓存读取/写入)
- 总体及各工具的工具调用延迟 p50/p95;会话时长 p50/p95
- token 用量最高的会话、时长最长的会话、重试次数(发生错误后重复执行相同的工具调用)
- 将提示词聚类为任务类型(构建、调试、部署、研究、写作、UI、审查、其他)
- 按项目(工作目录)对会话分组,并标记子智能体运行
如果日志未记录某项信息,写明“未记录”。绝不编造数字。
将结果保存为 harness-summary.json。

步骤 2. 生成单文件 dashboard.html(深色主题,带动态数字和图表):
- 概览栏:工具调用总数、提示词数、错误率、token 数、p95 延迟
- 追踪表:每个会话一行(工具、项目、开始时间、时长、提示词数、工具调用数、错误数、token 数、模型);支持搜索、按工具筛选、排序,以及隐藏子智能体运行的开关
- 追踪详情:点击会话,查看其各轮交互和工具调用的瀑布图,显示成功/错误状态及耗时
- 按项目统计的会话数、按模型展示的 token 用量时间趋势、模型表(token 数、错误率)
- 各工具的延迟视图,以及按工具和错误类型分组的错误浏览器
- 启发式评分(工具成功率、重试次数、各会话健康度),明确标注“启发式”
如果文件过大,将内嵌追踪数据限制为 token 用量最高的 200 个会话。

步骤 3. 根据数据编写 HARNESS.md,提出对 CLAUDE.md / AGENTS.md 的修改建议:
- 模型路由:根据我使用过的模型及失败情况,确定各任务类型应使用哪个模型
- 工具:保留(使用频繁、失败率低)、修复(失败率高)、移除(很少使用)
- 技能:为每种重复执行 3 次及以上的任务类型创建一个技能,包含一行触发条件和执行步骤
- 防护规则:我最常见的 3 种失败模式,以及分别预防它们的检查项
- 预算:消耗 token 最多的 5 个方面,以及分别减少其消耗的一项改动
为每条建议引用相应的会话依据。

步骤 4. 在修改任何配置之前,向我展示 5 个核心数字和拟议的 diff。我会每周审查,只做数据支持的修改。

--------提示词结束-------------
原文提示词(English)
the highest alpha play right now is so simple most people will never do it...

make a harness that works for YOU

it'll 10x the quality and speed of your AI outputs.

paste this ONE prompt into your agent:

---------start of the prompt----------------

Build me a Langfuse-style observability dashboard from my own AI coding sessions for the last 7 days.

SOURCES (read locally, read-only):
- Claude Code: ~/.claude/projects/**/*.jsonl
- Codex: ~/.codex/sessions/**/*.jsonl (and ~/.codex/history.jsonl)
Never print secrets, keys or full prompt text. Snippets max 10 words, with keys, paths, URLs and long ids stripped.

STEP 1. Write a stdlib-only Python script that computes, per tool:
- sessions per day, user prompts, tool calls by tool name, failed tool calls by tool and error type
- models used, tokens (input, output, cache read/write) per model per day
- tool-call latency p50/p95, overall and per tool; session length p50/p95
- top sessions by tokens, longest sessions, retries (same tool call repeated after an error)
- prompts clustered into task types (build, debug, deploy, research, writing, UI, review, other)
- sessions grouped by project (working directory), with subagent runs flagged
If a log doesn't record something, write "not logged". Never invent numbers.
Save the result as harness-summary.json.

STEP 2. Render a single-file dashboard.html (dark, animated numbers and charts):
- Summary strip: total tool calls, prompts, error rate, tokens, p95 latency
- Traces table: one row per session (tool, project, start, duration, prompts, tool calls, errors, tokens, model); search, filter by tool, sort, toggle to hide subagent runs
- Trace detail: click a session to see a waterfall of its turns and tool calls with ok/error and duration
- Sessions by project, tokens over time by model, a model table (tokens, error rate)
- Latency view per tool, and an error explorer grouped by tool and error type
- Heuristic scores (tool success rate, retries, per-session health), clearly labeled "heuristic"
Cap embedded traces at the top 200 sessions by tokens if the file gets too big.

STEP 3. From the data, write HARNESS.md proposing changes to CLAUDE.md / AGENTS.md:
- Model routing: which model for which task type, based on what I used and what failed
- Tools: keep (high use, low failure), fix (high failure), cut (rarely used)
- Skills: one for every task type I repeated 3+ times, with a trigger line and steps
- Guardrails: my top 3 failure patterns and a check that prevents each
- Budget: my top 5 token sinks and one change that would cut each
Cite the sessions behind each suggestion.

STEP 4. Show me the 5 headline numbers and the proposed diff before changing any config. I'll review weekly and change only what the data shows.

--------end of the prompt-------------
视频地址